
Crawlkit
CrawlKit empowers developers to effortlessly extract structured data from any website with a single API call.
Visit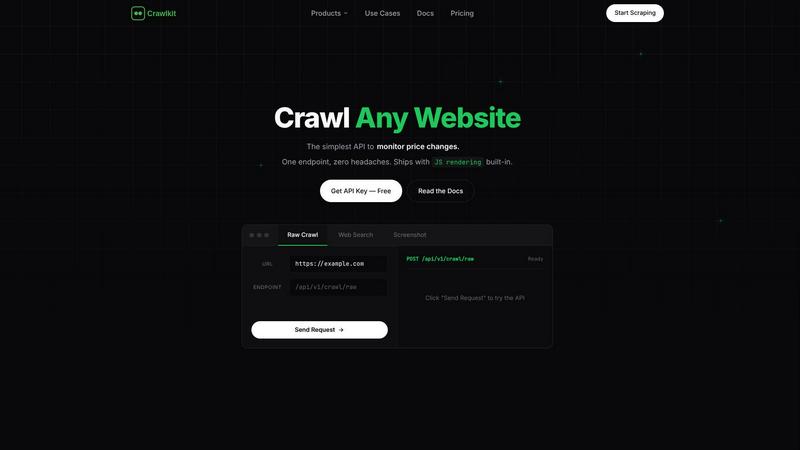
About Crawlkit
CrawlKit is an advanced web data extraction platform designed specifically for developers and data teams who require reliable and scalable access to web data without the hassles of managing intricate scraping infrastructure. In an era where web scraping presents numerous challenges such as rotating proxies, headless browsers, anti-bot protections, and rate limits, CrawlKit streamlines this process by automating the complex aspects of web scraping. When users send a request to CrawlKit, the platform manages proxy rotation, browser rendering, retries, and overcoming blocking mechanisms. This enables users to focus on leveraging the extracted data rather than worrying about the collection process itself. With CrawlKit, users can extract a wide array of web data through an intuitive interface, including raw page content, search results, visual snapshots, and structured professional data from platforms like LinkedIn. By providing a one-stop solution for web data extraction, CrawlKit empowers teams to turn the web into a powerful resource for insights and decision-making.
Features of Crawlkit
Automated Proxy Management
CrawlKit handles proxy rotation automatically, ensuring that your requests are anonymous and reducing the risk of being blocked by target websites. This feature eliminates the need for you to manage proxies manually, allowing for a seamless scraping experience.
Headless Browser Rendering
By utilizing headless browser technology, CrawlKit can render JavaScript-heavy websites fully, allowing you to extract dynamic content that traditional scrapers might miss. This feature is crucial for obtaining complete and accurate data from modern web applications.
Comprehensive API Integration
CrawlKit offers a simple HTTP API that can be integrated with any programming language or automation tool. This flexibility ensures that your existing workflows can incorporate web data extraction without any restrictions or lock-in.
Transparent Credit-Based Pricing
CrawlKit employs a straightforward credit-based pricing model, allowing users to know exactly what they are paying for. With no hidden fees or surprise charges, you can budget effectively while scaling your data extraction needs.
Use Cases of Crawlkit
CRM Enrichment
CrawlKit enables teams to enrich their CRM systems automatically by pulling detailed LinkedIn profile data. This includes job titles, company information, and contact details, helping sales teams qualify leads more effectively and streamline their outreach efforts.
Competitive Intelligence
Businesses can leverage CrawlKit to monitor competitor activities by extracting data from their websites and social profiles. This allows teams to gather insights on competitor strategies, product launches, and customer engagement, positioning them to make informed decisions.
Social Media Analytics
With CrawlKit, marketing teams can track social media performance by extracting follower counts, engagement metrics, and post details from platforms like Instagram. This data helps in analyzing trends and refining social media strategies for better results.
App Store Reviews Analysis
CrawlKit allows for the extraction of reviews and ratings from app stores such as Google Play and Apple App Store. This information can be utilized to assess user sentiment, identify common issues, and improve product offerings based on user feedback.
Frequently Asked Questions
What types of data can I extract using Crawlkit?
CrawlKit enables users to extract a variety of data, including raw page content, search results, visual snapshots, and structured data from social media platforms and app stores, all through a single API call.
Is there a limit on the number of API calls I can make?
CrawlKit offers a flexible credit-based pricing model with no monthly commitments or rate limits. You can scale your usage according to your needs without worrying about hitting a cap.
How does Crawlkit ensure data accuracy?
CrawlKit waits for full page loads and validates responses to ensure that users receive complete and accurate data. This approach minimizes the chances of dealing with partial or broken outputs.
Can I integrate Crawlkit with my existing tools?
Yes, CrawlKit is designed as a simple HTTP API, making it compatible with any programming language or automation tool. This flexibility allows for easy integration into your existing workflows without any restrictions.
Explore more in this category:
Similar to Crawlkit
CustomerFlows
A modern, AI-native CRM built for lead-driven businesses. Qualify leads 24/7, track pipelines, and measure true ad ROI with flat-rate pricing.
Context Board
Context Board brings your numbers, docs, clients, content and day into one workspace that Claude and Codex can read and update.
RunMyWealth
Free, private financial calculators for mortgage, FIRE, and debt. 100% free, runs locally in your browser, no signup required.
mcpfolio
Discover MCP servers, compare tools, and follow setup guides to connect AI assistants to your apps and workflows
Ecommerce Data API
Amazon research data APIs for developers, sellers and AI agents. Integrate product, keyword and market research through REST APIs and MCP.
APIKO AI API
One OpenAI-compatible endpoint for text, image and video models from OpenAI, Anthropic, Google, DeepSeek and more.
JevModel
Jev turns text or JSON into Choice, Score and Noul answers with probabilities.